Securing Legacy Applications Your Business Still Depends On
There is a server in almost every company I walk into that nobody wants to talk about. Sometimes it sits in a closet next to the mop sink. Other times, it lives in a rack at a colocation facility that the finance team keeps paying for out of habit. In many cases, it’s a virtual machine that someone cloned eight years ago and never touched again. When I ask the IT manager what runs on it, I usually hear a pause, followed by something like “that’s the billing system” or “don’t reboot that one.” Quite often, securing legacy applications like that one is the hardest job in the building.
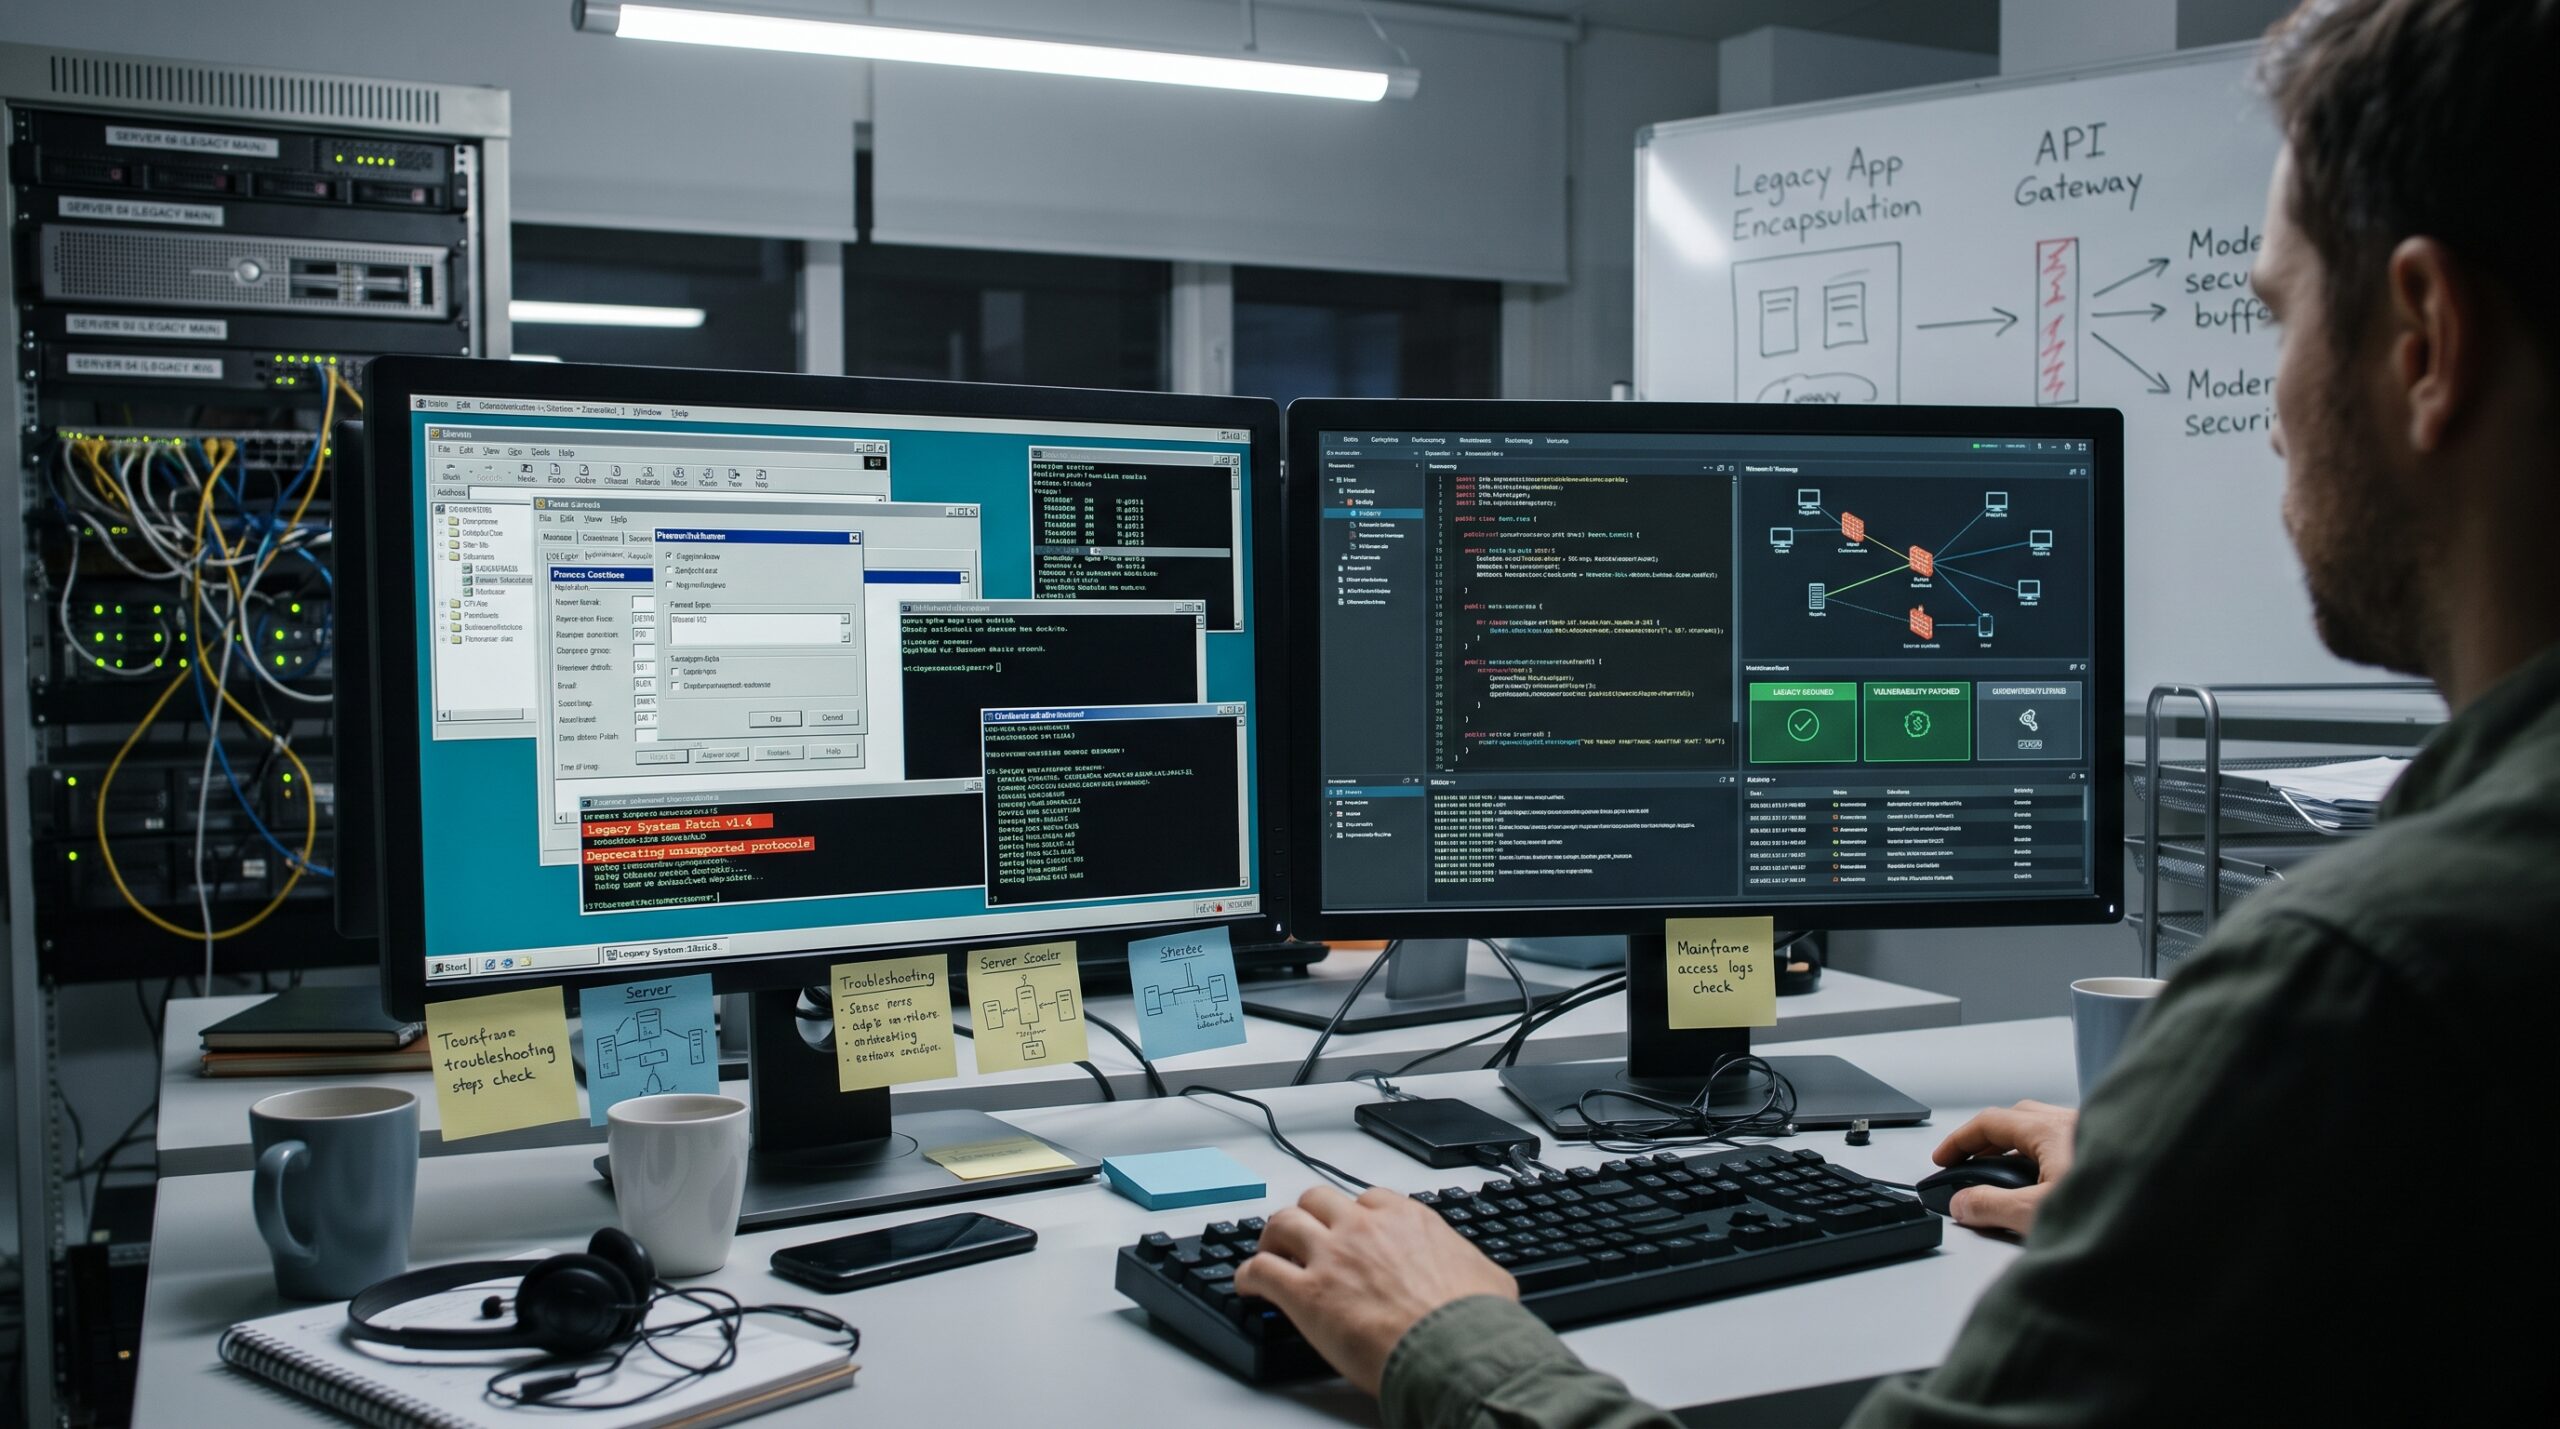
For most of my career as a cybersecurity architect, I have worked on exactly these systems. These include mainframe terminals, Visual Basic front ends, Java applets that refuse to die, and custom PHP portals built by a contractor who moved abroad a decade ago. However, my job is not to tell a business to throw them away. Instead, it’s to keep them running safely until the business is ready to replace them, and sometimes that day never comes.
This article covers how I actually approach securing legacy applications for consultancies, accounting practices, staffing agencies and other professional services firms. In other words, it’s for businesses that run on software older than some of their employees. There’s no vendor pitch here and no fantasy that you can modernize everything by next quarter. Instead, it’s just the work.
Why Securing Legacy Applications Gets Harder Every Year
Legacy applications don’t get worse on their own. After all, the code is the same code it was on the day it shipped. What changes, however, is everything around it.
For example, when a vendor declares a product end of life, they’re telling you that any flaw discovered from that point forward stays a flaw forever. For this reason, the Cybersecurity and Infrastructure Security Agency put this at the very top of its Bad Practices catalog. In fact, CISA’s first two bad practices were using unsupported or end of life software, and using known, fixed or default passwords and credentials. Unfortunately, I’ve seen both on the same box more times than I can count.
Attackers also understand this better than most boards do. Writing in Dark Reading, one security leader pointed out that application inventories include apps that may not have had a code change in years, and that certainly weren’t built with modern DevSecOps processes, and attackers are happy to exploit that.
Then there’s the money. According to IBM, the global average cost of a data breach fell to $4.44 million, while the average U.S. breach reached a record $10.22 million. For a midsize consulting firm, therefore, a number like that isn’t just a bad quarter. Instead, it can end the company.
The uncomfortable truth is that legacy systems usually hold the most valuable data in the building. Think, for instance, of twenty years of client records, payroll history, contracts, pricing models and intellectual property. As a result, securing legacy applications often matters more than protecting the newest SaaS tools you bought last year, which may hold far less data than the old database underneath your practice management system.
The Mindset Shift: Securing Legacy Applications From the Outside In
Here’s the first thing I tell every client. In most cases, securing legacy applications doesn’t mean fixing the application itself. Instead, you’re going to secure everything around it.
At first, that sounds like defeat, but it isn’t. With modern software, security lives inside the code through input validation, authentication libraries, encryption at rest and patch cycles. With legacy software, on the other hand, you often can’t touch the code. For example, the source might be lost, the compiler might not run on any supported operating system, or the one developer who understood it may have retired to Arizona.
Because of this, the strategy changes. You treat the legacy application as a fragile, valuable object and then build layers of protection around it. Think, for example, of a museum displaying a manuscript that is centuries old. Nobody tries to make the paper stronger. Instead, they control the humidity, the lighting and who can get near it, and meanwhile they watch it constantly.
Similarly, OWASP makes the same point about web applications. From a purely technical perspective, the top remediation strategy is to fix the vulnerability in the application’s source code; unfortunately, in real business situations, updating the source code is often not easy. That gap between the ideal and the real, in short, is where my work happens.
Step One: Take Inventory Before Securing Legacy Applications
First of all, securing legacy applications starts with knowing what you have, because you can’t protect what you can’t name. That sounds like a cliché until you run your first real discovery exercise and find fourteen applications nobody on the current IT team knew existed.
As Infosecurity Magazine put it, you can only start addressing risk in legacy apps when you know what and where they are.
When I build an inventory for a client, I’m not just listing application names. Instead, for every system, I want to know:
- First, what business process depends on it, and what happens if it’s down for a day, a week or a month
- Next, who the actual users are, rather than who the org chart says they should be
- Also, what data it stores, processes or passes along
- In addition, what operating system, runtime and database it sits on, with exact versions
- Similarly, what it talks to over the network, both inbound and outbound
- Furthermore, who supports it today, whether that’s a vendor, a contractor or nobody
- Finally, whether anyone still has admin credentials and where those credentials live
The Index Card Problem
That last point, in particular, matters more than people expect. For example, at a regional accounting practice I worked with, the only administrator password for their document archive was written on an index card. Worse still, the card was taped inside a desk drawer belonging to someone who had left the firm three years earlier. On top of that, it was a default password the vendor had shipped with the product. Put simply, that’s two CISA bad practices on one index card.
Therefore, expect the inventory to take longer than you planned. Also, talk to the people who use the systems every day, not just IT. After all, the office manager often knows more about what’s really running than the network diagram does.
Step Two: Rank Your Risk Honestly
Of course, not every legacy application deserves the same attention. A read only reporting tool used by three people in a back office, for instance, isn’t the same risk as a client portal exposed to the internet on an operating system Microsoft stopped patching years ago.
That’s why I score each system on three questions:
Exposure. Can someone reach it from the internet, from the guest WiFi, or from any workstation on the corporate network? Naturally, the wider the reach, the higher the score.
Value. What would an attacker gain? They might get, for example, client financial data, credentials that open other systems, or a path toward the domain controller.
Known weakness. Are there publicly documented vulnerabilities for this platform that attackers are actually using?
For that third question, I rely heavily on CISA’s Known Exploited Vulnerabilities catalog. In fact, CISA advises organizations to use the KEV catalog as an input to their vulnerability management prioritization. So if your legacy platform shows up there and the entry links it to ransomware campaigns, it moves to the top of the list, no matter how inconvenient that is.
Once you’ve scored everything, you’ll usually find that a small handful of applications carry most of your risk. Therefore, focus your effort on securing legacy applications at the top of that list first. After all, trying to fix everything at once is how security programs stall.
Step Three: Isolate Before You Do Anything Else
If I could only make one change in a legacy environment, it would be network segmentation. Simply put, nothing else gives you as much protection for the effort.
Most legacy applications were designed for a world where the network perimeter was the security model. In that world, anything inside the firewall was trusted. Although that assumption has been dead for years, the software still doesn’t know it.
Segmentation, therefore, means putting each risky legacy system into its own network zone, with firewall rules that allow only the specific traffic it needs. For example, the billing server talks to the database server on one port. Likewise, a defined group of users reaches the application through one gateway. Meanwhile, everything else is denied by default.
Map Dependencies Before You Lock Anything Down
A common objection, of course, is “we tried that and it broke things.” Usually, though, that’s because nobody mapped the dependencies first. So before you lock anything down, run the system in a monitoring mode for a few weeks and record every connection it makes. As a result, you’ll find surprises, such as the nightly job that sends a file to a partner over FTP or the printer that receives invoices directly. Then document all of it and write rules that allow only what’s legitimate.
Microsoft’s zero trust guidance, likewise, treats this as a basic expectation. Specifically, when securing access to sensitive legacy applications that use Integrated Windows Authentication, LDAP, Kerberos or similar protocols, Microsoft says to assume these environments are vulnerable and to implement layered controls.
In short, assume it’s vulnerable. That’s the right default for securing legacy applications you can’t patch.
Step Four: Put Modern Identity in Front of Old Logins
In my experience, weak authentication is the most common problem I find when securing legacy applications. Typically, that means shared accounts, passwords that never expire, no lockout after failed attempts and almost never any form of multifactor authentication.
While you usually can’t add MFA to the application itself, you can put it in front of the application. A few approaches work well in practice:
Application proxies. Here, a modern identity provider sits in front of the legacy app, handles login with MFA and conditional access, and then passes the user through. As a result, the application thinks it’s getting a normal session, while every access request goes through modern identity checks first.
Jump hosts and privileged access workstations. Similarly, for administrative access to legacy servers, require admins to connect through a hardened, monitored jump host that enforces MFA. In other words, no direct remote desktop from laptops.
Remote access gateways. Finally, if remote users need the application, give them a gateway that verifies identity and device health. That way, you avoid a flat VPN that drops them onto the whole network.
In addition, I push hard on retiring shared accounts. After all, if five people log in as “admin,” your audit logs are useless. So give everyone their own credentials, even if it means buying a few extra licenses. Eventually, you’ll want that accountability the day something goes wrong.
Step Five: Virtual Patching for Securing Legacy Applications
Even when a vulnerability is found in software you can’t update, you still have options. Virtual patching, for example, is one of the most useful tools for securing legacy applications, yet it’s also one of the most misunderstood.
To begin with, OWASP defines virtual patching as a security policy enforcement layer that prevents the exploitation of a known vulnerability. In plain terms, you put a filter in front of the application that recognizes and blocks the specific attack. Consequently, the malicious request never reaches the vulnerable code.
Moreover, virtual patches can be deployed at the network level using the intrusion prevention features in a next generation firewall, a web application firewall or a standalone intrusion prevention appliance.
Lessons From Real WAF Deployments
For web applications in particular, a well tuned web application firewall is often the best investment you’ll make. That said, here are a few hard lessons from deploying them:
- Don’t rely on default rule sets alone. Generic rules, after all, catch generic attacks, so write specific rules for the specific weaknesses in your application.
- Run in detection mode first. Because old applications do strange things with input, a rule that looks harmless can block a form submission your sales team depends on.
- Treat virtual patches as temporary. In other words, they buy time, but they’re not a substitute for a modernization plan, and they also need upkeep as attack techniques change.
- Test them. Finally, have someone attempt the actual exploit against a test copy of the application and confirm it’s blocked.
How It Played Out for One Staffing Agency
I once worked, for example, with a staffing agency whose candidate portal ran on a framework with a widely known injection flaw. Unfortunately, the vendor was gone, and rewriting the portal was a nine month project. So we put a WAF rule in front of it in two days and confirmed the exploit was blocked. As a result, the business had breathing room to plan the rewrite properly instead of rushing it.
Step Six: Watch Everything, Because You Can’t Prevent Everything
With legacy systems, you have to accept that some attack will eventually get further than you’d like. While prevention matters, detection and response are what limit the damage.
Indeed, the IBM data supports this. The breach lifecycle dropped by 17 days to 241 days as more organizations detected breaches internally. Furthermore, internal detection saved an average of $900,000 compared to breaches disclosed by attackers.
What I Monitor on Legacy Hosts
When securing legacy applications, however, monitoring often has to be creative, since the systems themselves log poorly or not at all. Here, then, is what I typically put in place:
Network monitoring at the segment boundary. Since you’ve already isolated the system, watch every connection crossing that boundary. A billing server that suddenly connects to an unfamiliar external address at 3 a.m., for instance, is a story worth reading.
File integrity monitoring. In addition, track changes to executables, configuration files and scheduled tasks on the legacy host. After all, on a system that hasn’t been updated in years, any change is suspicious.
Database activity monitoring. Likewise, if the application can’t tell you who exported ten thousand client records, the database layer often can.
Log forwarding. Whatever logs the system does produce, ship them off the box immediately to a central platform. Otherwise, attackers may clean up local logs on old servers, which they love to do.
Above all, make sure someone actually looks at the alerts. I’ve audited companies, for example, with excellent monitoring tools that nobody had opened in six months.
Step Seven: Encrypt the Data and Shrink the Blast Radius
Many legacy applications store data in plain text, or with encryption that seemed fine in 2005 but is trivial to break today. Although you may not be able to change how the application stores data, you can still protect it at other layers. In fact, encryption is one of the most overlooked parts of securing legacy applications.
For example, full disk encryption on the host protects against stolen drives and some backup exposure. Similarly, transparent encryption at the database level, where the platform supports it, protects data files at rest. Furthermore, wrapping the application’s network traffic in TLS through a reverse proxy protects data in transit, even when the application only speaks plain HTTP internally.
Just as important, however, is data minimization. In other words, ask whether the legacy system really needs to keep all that history. I’ve helped clients, for instance, move fifteen years of closed client records off a vulnerable system and into a properly secured, read only archive. As a result, the application kept running with the data it actually needed, and the potential damage from a breach shrank dramatically.
Securing Legacy Applications Within a Zero Trust Plan
Naturally, every client asks me whether zero trust is realistic when half their environment is old software. The short answer is yes, but not the way vendors usually sell it.
To start, NIST describes a zero trust strategy as one that grants no implicit trust to systems based on their physical or network location. Legacy applications, however, were built on exactly that kind of implicit trust. That’s why, at first glance, the two seem incompatible.
Still, NIST itself is practical about this. As SecurityWeek reported, NIST suggests organizations implement zero trust principles incrementally and operate in a hybrid zero trust and legacy mode during the transition.
In reality, that hybrid mode is where most businesses will live for years. Everything I’ve described above, from segmentation and identity proxies to virtual patching and continuous monitoring, is really just securing legacy applications through zero trust principles they can’t enforce on their own. So you aren’t making the old application trust less. Instead, you’re building a trust broker around it that does the verifying on its behalf.
Governance: The Part of Securing Legacy Applications Everyone Skips
Without ownership, technical controls fail. For this reason, every legacy application needs a named business owner outside IT. That person is accountable for the risk the system carries and signs off on the decision to keep it running.
In addition, I recommend a formal risk acceptance process. So when the business decides to keep an end of life system in production, that decision should be written down and approved by leadership. Furthermore, it should have an expiry date and be reviewed at least once a year. This, in turn, does two things. First, it forces honest conversations about cost and risk. Second, it protects the IT team when something goes wrong with a system they flagged years ago.
Planning the Exit and the Budget
Similarly, Dark Reading’s guidance stresses having security policies for removing legacy apps, which is an area most organizations neglect. Decommissioning, therefore, should be a planned process. That means you export and archive the data, revoke every credential, remove firewall rules, wipe the storage and then update the inventory. After all, partly retired systems, the ones nobody uses but nobody turned off, are some of the easiest targets I find during assessments.
Finally, budget for securing legacy applications the same way you budget for rent. One approach Dark Reading describes, for example, is setting aside a small share of each team’s capacity for legacy code and security work on a regular basis. In the long run, steady, boring progress beats heroic cleanups that happen once.
When It’s Finally Time to Replace It
Ultimately, securing legacy applications is a bridge, not a destination. While every control above buys time and reduces risk, none of them makes an end of life system safe forever. Eventually, the cost of protecting the old system plus the risk it still carries will exceed the cost of replacing it.
For that reason, I tell clients to watch for these signals:
- First, the compensating controls cost more each year than a modern replacement would cost to run
- Second, the operating system or hardware can no longer be sourced or supported at any price
- Also, a regulator, insurer or major client starts asking pointed questions you can’t answer comfortably
- In addition, the knowledge needed to keep the system alive lives in only one or two people’s heads
- Finally, a serious exploitable flaw appears that no virtual patch can reliably block
When those signals line up, start the migration plan. Even then, however, keep every protective layer in place until the old system is completely gone. After all, migrations are a dangerous period. Data gets copied to temporary locations, for example, firewall rules get loosened “just for the cutover,” and test environments end up holding production data. Therefore, plan security into the migration with the same care you put into the protections that kept the old system alive.
A Final Word on Securing Legacy Applications
In the end, the legacy systems in your business aren’t failures. On the contrary, they’re the reason the business survived long enough to have legacy systems. Indeed, they hold the institutional memory, the client relationships and the processes your people know by heart.
At the same time, they carry risk that grows every year, quietly, until something happens. Admittedly, securing legacy applications isn’t glamorous work. Nobody, for instance, gives awards for a well documented firewall rule or a carefully tested WAF policy. Yet in my experience, these are exactly the controls that decide whether an attack becomes a minor incident report or a headline.
So start with the inventory. Next, isolate what’s exposed. Then put modern identity in front of old logins and watch everything. Finally, give every old system an owner and an honest plan for the day it finally retires.
Frequently Asked Questions
What counts as a legacy application?
Generally, it’s any software still in use that the vendor no longer supports, that runs on an unsupported operating system or runtime, or that your team can no longer safely update. Put simply, supportability defines it more than age does. In fact, CISA’s Bad Practices guidance treats unsupported software as one of the most dangerous conditions an organization can have.
Can securing legacy applications be done without changing their code?
Yes, in most cases. For example, network segmentation, identity proxies with MFA, web application firewalls and continuous monitoring all protect the application from the outside. Similarly, OWASP’s Virtual Patching Best Practices explains how to block known exploits without touching source code.
Is virtual patching a permanent fix?
No. Instead, it’s a compensating control that buys time while you plan a real remediation or replacement. Furthermore, rules need ongoing tuning and testing as attack techniques evolve. For more detail, eSecurity Planet’s overview of virtual patching covers where it fits and its limits.
How do I decide which legacy system to secure first?
First, rank each one by exposure, data value and known exploited weaknesses. Then check your platforms against the CISA Known Exploited Vulnerabilities Catalog. As a rule, anything listed there and reachable from the internet goes to the top.
Does zero trust work with legacy systems?
Yes, as long as you apply it gradually. In fact, NIST’s Zero Trust Architecture publication recognizes that most organizations will run a hybrid of zero trust and legacy environments during the transition.
How much could a breach through a legacy system cost my business?
According to IBM’s 2025 research, summarized by Help Net Security, the U.S. average breach cost reached a record $10.22 million. However, faster internal detection significantly reduced that figure.
References
- Cybersecurity and Infrastructure Security Agency. Bad Practices
- Cybersecurity and Infrastructure Security Agency. Known Exploited Vulnerabilities Catalog
- National Institute of Standards and Technology. Zero Trust Architecture
- OWASP Foundation. Virtual Patching Best Practices
- Help Net Security. Average Global Data Breach Cost Now $4.44 Million
- Dark Reading. Legacy Apps: The Security Risk Lurking in Dusty Corners
- Infosecurity Magazine. Forgotten, But Not Gone: The Security Risk of Legacy Apps
- eSecurity Planet. What Is Virtual Patching and How Does It Work?
- SecurityWeek. NIST’s Zero Trust Taxonomy Introduces Components, Threats and Migration Routes
- Microsoft. Zero Trust Assessment Guidance: Securing Legacy Application Access